cgroup v2 does not like your old code
Everybody knows that upgrading to the latest version of a framework is important for several reasons like security enhancement, performance optimizations, support from vendor, access to new features and more.
Another but less tangible reason we should upgrade our code is future-proofing. For example, by upgrading to the latest version of the .NET Framework, you position your application to take advantage of new features, and improvements but also remain compatible with upcoming tools, and platforms.
The case of Kubernetes 1.25
If you run a Google search like “Kubernetes 1.25 memory consumption” you will find multiple users lamenting memory pressure after the Kubernetes upgrade to the version 1.25. Pods became hungry, users are facing a keep growing memory consumptions sometimes taking double of the resource defined by the requests. Depending on the defined pod limits and the cluster configuration you might also face OOMKill and in the worst situation reach the maximum cluster scale and get new deployments blocked. What we are facing it is not a problem related to AKS or the .NET framework but a general Linux issue.
Microsoft provides a solution to this issue on the following article.
- The root cause can be put this way: cgroupsv2 does not like your old code.
- The solution is pretty straightforward: update your code to Java/.NET code to the latest framework versions!
This issue is also mentioned in the AKS release notes where Microsoft advises to carefully test your application for cgroupsv2 before moving to 1.25.*. If your solution is running on an old framework, be aware the time is ticking because the AKS 1.24 will be deprecated at the end of July 2023 therefore to stay compliant with the AKS support policy (and to avoid waste of resources) you need to upgrade your application code.
Gain time with a temporary fix
Ensuring the framework and the application’ dependencies are up to date is the responsibility of every development team. However, there may be situations where upgrading the code is not feasible in the short period due to various reasons such as the size of the solution, cost implications, or other constraints. In such cases, it is essential to explore alternative solutions.
Microsoft provides a temporary fix : apply a run-once Daemonset to revert the cgroup to v1. The Daemonset by default will applied to all nodes in your cluster and will reboot them to apply the change. Therefore, in order to avoid disruptions to your applications, we advise to create new nodepool(s) in combination with a nodeSelector to better control how to rollout the fix.
With the following steps, we will see how to apply the fix to our user node pool. We will not revert the cgroup on the system poolas the issue primarily lies with the application workloads that typically run on the user pool. Before proceeding, take the time to analyze whether your applications are high available, which HA techniques are used and what are the potential drain-blockers (e.g. pod disruption budget).
A safe way to roll-back to cgroup v1 is the following.

- Create a new “buffer” node pool with the desired SKU. (example)
- Cordon the existing nodes. Cordoning marks existing nodes as “SchedulingDisabled” to prevent any pods from being added to the nodes.
- Drain the existing nodes toward the “buffer” pool. Draining nodes will cause pods running on them to be evicted and recreated on the other, schedulable nodes.
- Upgrade the original nodepool by applying the Daemonset (with node selector)
- Uncordon the original pool.
- Cordon the nodes in the “buffer” pool.
- Drain nodes. Our applications will be .moved back to the original node pool now reverted to cgroup v1
- Delete the “buffer” node pool
Now that we are back to the cgroup v1, memory is not anymore under pressure, no more OOMKill, everything is green 🟢 and the reverted nodes are labeled with cgroup-version=v1.
You can find all the different steps along with the commands on this GitHub repo
So far so good?
So far so good. But what will happen next time we upgrade AKS (e.g. to 1.26)? Will we get back to the future? Yes, by triggering the upgrade procedure, the cluster nodes will be re-imaged meaning the cgroup v2 will be reinstated.
The potential of facing the same problem again in 3 to 6 months further emphasizes that reverting to cgroup v1 cannot be considered a permanent solution, but rather a temporary workaround to buy some time to complete the application migration to a new and more performant framework. Migration that might be complex and time-consuming, requiring careful planning and execution.
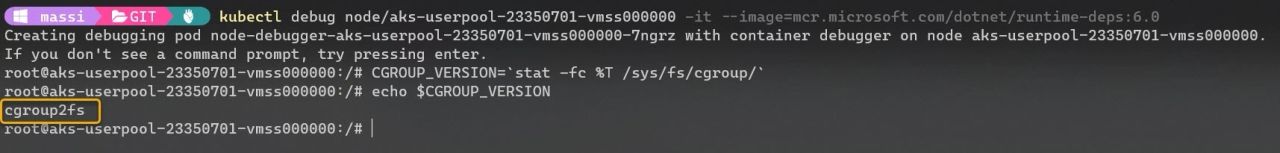
To check which version of cgroup you are running, create an interactive shell connection to one of your node as described here and get the version by running this command “CGROUP_VERSION=stat -fc %T /sys/fs/cgroup/”.
How about Kubernetes-based managed services?
Services like Azure Container Apps that are running on top of Kubernetes might face the same memory pressure problem. In that case we only have two options : either allocate more resources (and pay for it) or update your code.
Conclusion
Cloud is a moving target where technologies, services, and best practices are continuously changing and improving. To stay relevant and take full advantage of the benefits offered by the cloud, it is imperative to evolve and keep pace with these changes. By staying current with development frameworks, you position yourself to take advantage of future enhancements, remain compatible with upcoming technologies and in this specific case avoid to waste resources (and pay for it).
Photo by Uljana Borodina on Unsplash